Advanced Bot Handling
Resilient browser orchestration, proxy strategy, session management, and challenge handling for collecting permitted data from complex sources.
We engineer robust scraping architectures and API integrations that navigate complex data sources, stream real-time results, and scale without breaking. Built for teams that need clean data—not maintenance headaches.
Validated 2,408 records
WebSocket delivery active
Schema integrity confirmed
Reliable data collection requires more than a script. We design the orchestration, recovery, validation, and delivery layers that keep production pipelines running.
Resilient browser orchestration, proxy strategy, session management, and challenge handling for collecting permitted data from complex sources.
Move beyond batch files with live WebSocket pipelines designed for instant capture, transformation, retry protection, and delivery.
Transform raw HTML, documents, and media into validated records using deterministic rules, OCR, and LLM-assisted enrichment.
Not demo scripts—working data systems designed around scale, unreliable sources, strict schemas, and the way your team actually uses the output.
A mobile-first collection workflow captured account data, validated every record, and delivered clean results directly into the client’s database—on an urgent timeline.
Zillow listings matched against AirDNA projections, normalized by address, and filtered into a focused shortlist of high-potential rental opportunities.
Live comments captured, transformed into structured events, and delivered over WebSockets with retry logic to keep downstream applications current.
{
  "property_id": "SR-84720",
  "source_match": {
    "zillow": "verified",
    "airdna": "verified"
  },
  "address": "Miami, FL",
  "valuation": 685000,
  "annual_revenue": 76420,
  "confidence": 0.984,
  "status": "validated"
}From high-volume real estate data matching to checkpointed regulatory databases, we build for the failure modes that ordinary scripts ignore.
Cross-source property matchingZillow and AirDNA records normalized into a consistent, validated schema.
Checkpointed data collectionSQLite-backed NASBA CPAverify workflows that resume safely after interruptions.
Delivery that fits your stackStructured data shipped to JSON, databases, sheets, APIs, or live WebSockets.
Each stage owns a specific failure mode—from unstable sessions at the source to interrupted delivery downstream.
Route validated records into automations, databases, internal tools, or live applications without another manual handoff.
Explore infrastructure →Feedback from clients who needed fast delivery, careful execution, and dependable output—not another fragile scraper.
Within less than two days, he was able to scrape more than 20,000 account details and present them in a perfect format. 1000/10.
Muhammad hit every deadline and was even early for two of them. 10/10.
It’s been a pleasure, and I look forward to future collaborations.
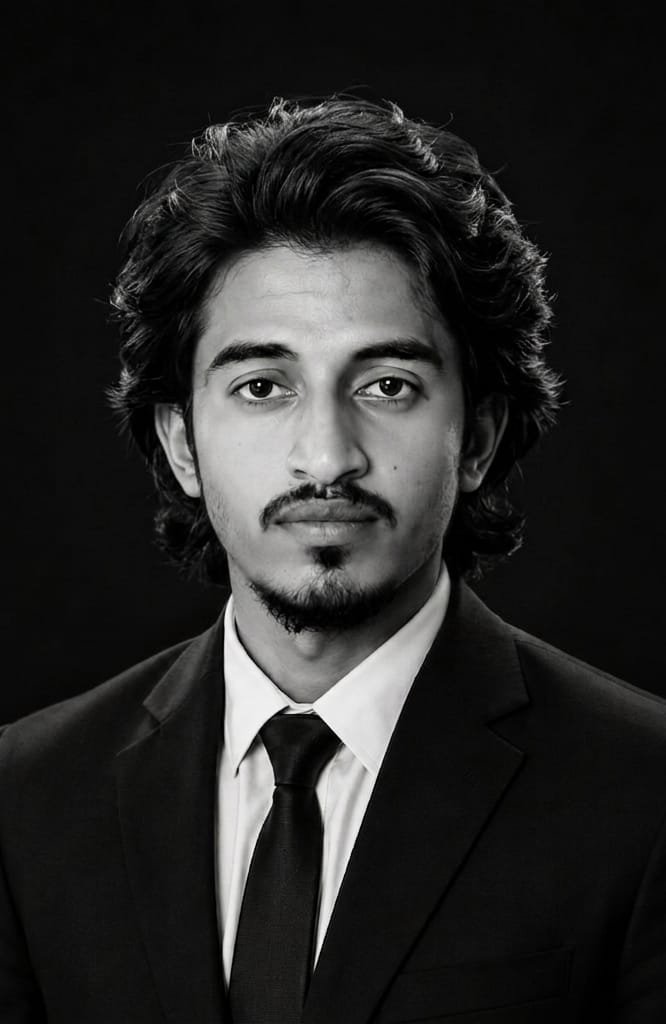
I’m Muhammad Shahbaz Akhtar, founder and data systems engineer at SourceRivet. After working across more than 200 websites, portals, APIs, and applications, I’ve learned that extraction is only the beginning. The real engineering starts with interruptions, changing structures, inconsistent records, and delivery failures.
“I design every pipeline around the edge cases: preserve completed work, make failures observable, and keep recovery practical.”
A focused four-step engagement keeps scope clear, proves feasibility early, and moves your project into production without unnecessary meetings.
Send the website, portal, API, app, or documents—and explain the business outcome you need.
We confirm feasibility, define the schema, and provide sample records before the full build begins.
The extraction, quality checks, retries, and recovery logic are engineered as one reliable system.
Receive clean data through CSV, JSON, database, API, or WebSocket—with support when sources change.
Clear answers about maintenance, reliability, access constraints, and what happens after the first successful run.
Ask a technical question →Source-specific selectors and parsing rules are isolated from the rest of the pipeline, so they can be repaired without rebuilding delivery, storage, or validation. For maintained systems, changes are investigated against saved examples and current source behavior.
Response and repair targets are agreed before launch based on run frequency and business criticality. Critical daily or live pipelines can include priority maintenance; no fixed SLA is promised unless it is explicitly included in the engagement.
The strategy is source-specific and rate-aware. Stable session identity, controlled concurrency, proxy health, and retry limits are preferred over unnecessary IP churn. Collection is designed for authorized and permitted use.
Feasibility is evaluated first. Depending on the authorized access available, the system may use stable browser sessions, client-provided credentials, permitted APIs, or human-in-the-loop challenge handling. We do not promise access where a source does not authorize it.
Common destinations include JSON, CSV, Google Sheets, SQLite, PostgreSQL, REST APIs, webhooks, and live WebSockets. Webhooks can trigger tools such as n8n, Zapier, and Make.
Yes. Existing Python, Selenium, Playwright, or API-based projects can be audited for the actual failure point, then repaired or restructured where the current design makes maintenance unreliable.
Book a 15-minute technical scoping call. No sales reps—just an engineering discussion about your extraction needs.
Book a Technical Call Usually replies within one business day.